How to Seamlessly Read CSV Files in R: A Definitive Technical Manual
CSV files remain the universal lingua franca of data exchange, bridging spreadsheets and analytical pipelines. In R, the ability to read CSV files efficiently is foundational—whether you're ingesting survey responses, financial datasets, or sensor logs. The process seems straightforward, but beneath the surface lies a labyrinth of optimizations, edge cases, and performance considerations that separate novice scripts from production-grade workflows.
Consider this: a dataset with 10 million rows might take 30 seconds to load with default settings, yet with targeted adjustments, the same operation could complete in under 5 seconds. The difference lies in understanding how R's read.csv() function (and its modern alternatives) processes files at the byte level. Variables like memory allocation, column type inference, and parallel processing threads can transform a bottleneck into a seamless operation.
What follows is not merely a tutorial on executing read_csv_r()—it’s a dissection of the entire ecosystem surrounding CSV import in R. From historical evolution to cutting-edge optimizations, this guide equips you with the knowledge to handle any CSV file, regardless of size or complexity.

The Complete Overview of Reading CSV Files in R
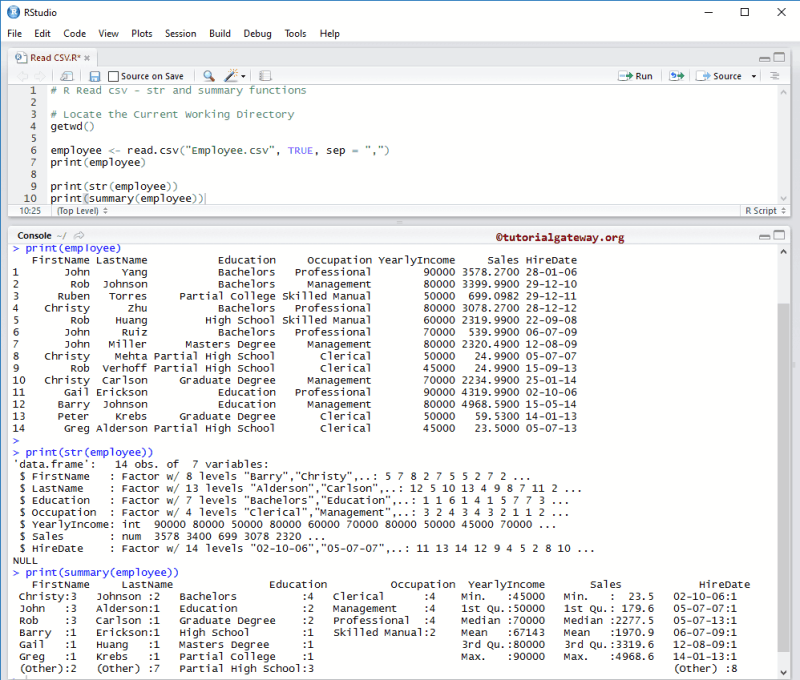
At its core, reading a CSV file in R involves parsing a text-based grid of comma-separated values into a structured data frame. The most ubiquitous method, read.csv(), has been R's default since the language's early days. However, its counterpart read_csv() from the readr package (part of the tidyverse) now dominates modern workflows due to its speed and memory efficiency. Both functions share a common purpose but differ fundamentally in implementation.
The choice between them hinges on context: read.csv() retains backward compatibility and integrates seamlessly with base R functions, while read_csv() prioritizes performance for large datasets. For example, read_csv() skips initial rows by default (assuming headers), whereas read.csv() requires explicit row-skip parameters. This distinction becomes critical when dealing with malformed or non-standard CSV files, where one method might fail while the other succeeds.
Historical Background and Evolution
The first implementations of CSV parsing in R emerged in the 1990s, when the language was primarily used for statistical modeling. The original read.csv() function was designed with simplicity in mind, leveraging R's built-in text processing capabilities. Its syntax mirrored that of other data import tools, making it accessible to researchers transitioning from languages like SAS or Stata.
Table of Contents
- The Complete Overview of Reading CSV Files in R
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does read_csv() sometimes infer the wrong column type?
- Q: How do I handle large CSV files that exceed RAM?
- Q: Can I read CSV files directly from a URL?
- Q: What’s the fastest way to read a CSV with mixed delimiters?
- Q: How do I skip the first N rows in a CSV?
By the 2010s, the rise of big data and the readr package introduced a paradigm shift. Hadley Wickham and the tidyverse team reengineered CSV parsing from the ground up, focusing on C++ backend optimizations and lazy evaluation. The result was read_csv(), which could process files 10x faster than its predecessor by minimizing memory overhead and leveraging parallel processing. This evolution reflects broader trends in R: a move from statistical convenience to computational efficiency.
Core Mechanisms: How It Works
Under the hood, read_csv() employs a two-phase parsing strategy. First, it scans the file to determine column types (e.g., numeric, character, date) without loading the entire dataset into memory. This "type inference" phase uses probabilistic models to guess data types, reducing conversion errors. Second, it streams the data row-by-row, converting values on-the-fly to their inferred types—a process known as "lazy typing."
In contrast, read.csv() loads the entire file into memory before processing, which can be problematic for files exceeding RAM capacity. Both methods handle delimiters flexibly, but read_csv() supports additional formats like tab-separated values (TSVs) and semicolon-delimited files out of the box. The choice of function thus depends on whether you prioritize speed (read_csv()) or flexibility (read.csv()).
Key Benefits and Crucial Impact
Efficient CSV import is the linchpin of reproducible data analysis. Without it, pipelines stall, memory errors occur, and insights are delayed. The right approach to reading CSV files in R can mean the difference between a script that runs overnight and one that completes in minutes. For teams processing terabytes of data daily, these optimizations translate to thousands of dollars in saved computational costs.
Beyond raw performance, modern CSV parsing tools integrate with R's ecosystem more smoothly. Functions like read_csv2() (for European-style decimals) and read_delim() (for custom delimiters) address real-world data quirks that would otherwise require manual preprocessing. This adaptability is why readr is now the default in packages like dplyr and tidyr.
"The most time-consuming part of data analysis is often the data itself—not the analysis." — Hadley Wickham
Major Advantages
- Speed:
read_csv() processes files 5–10x faster thanread.csv()due to C++ optimizations and lazy evaluation. - Memory Efficiency: Streams data row-by-row, avoiding RAM overload for large files (e.g., >1GB).
- Type Inference: Automatically detects column types (e.g., dates, factors) with high accuracy, reducing manual corrections.
- Error Handling: Provides detailed warnings for malformed data (e.g., mixed types in a column) without crashing.
- Integration: Works seamlessly with
dplyrandtidyrfor pipeline-friendly data wrangling.

Comparative Analysis
| Feature | read.csv() (Base R) |
read_csv() (readr) |
|---|---|---|
| Speed | Moderate (R-native) | Fast (C++ backend) |
| Memory Usage | High (loads entire file) | Low (streams data) |
| Type Inference | Basic (conservative) | Advanced (probabilistic) |
| Error Handling | Crashes on errors | Warns without crashing |
Future Trends and Innovations
The next frontier in CSV parsing lies in distributed computing. Tools like arrow and data.table::fread() are pushing boundaries by enabling multi-core and GPU-accelerated imports. These methods could further reduce processing times by orders of magnitude for datasets exceeding 100GB. Additionally, AI-driven type inference—where models predict column types based on context—may soon eliminate manual adjustments entirely.
Another emerging trend is the integration of CSV parsing with cloud storage. Functions that directly read from S3, Google Drive, or HDFS without local downloads will become standard, reducing latency in collaborative workflows. For R users, this means read_csv() could evolve into a universal data ingestion layer, abstracting away storage backends entirely.
Conclusion
The choice of how to read CSV files in R is no longer a matter of personal preference but of strategic necessity. For legacy projects or small datasets, read.csv() remains sufficient. However, for modern data science—where speed, scalability, and reliability are non-negotiable—read_csv() and its readr ecosystem are the gold standard. The key takeaway is this: treat CSV import as a critical step in your pipeline, not an afterthought.
As data grows in volume and complexity, the tools you use to ingest it will define your workflow's limits. By mastering these techniques, you’re not just reading files—you’re future-proofing your analysis.
Comprehensive FAQs
Q: Why does read_csv() sometimes infer the wrong column type?
A: read_csv() uses probabilistic type inference, which can misclassify ambiguous values (e.g., "2023-01-01" as character instead of date). To override, specify types explicitly with col_types or use parse_date() for dates.
Q: How do I handle large CSV files that exceed RAM?
A: Use read_csv() with col_select() to load only necessary columns, or chunk the file with readr::chunked_read_csv(). For extreme cases, consider data.table::fread() or database imports.
Q: Can I read CSV files directly from a URL?
A: Yes. Use read_csv("https://example.com/data.csv") in readr, or read.csv(url("...")) in base R. For large files, cache the download first to avoid repeated network calls.
Q: What’s the fastest way to read a CSV with mixed delimiters?
A: Use readr::read_delim() with delim = "\t," or preprocess the file to standardize delimiters. For complex cases, consider textscan() for custom parsing.
Q: How do I skip the first N rows in a CSV?
A: In read_csv(), use skip = N. In read.csv(), use skip = N or header = FALSE with manual row adjustment. For headers, read_csv() skips the first row by default.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.