How to Seamlessly Bring CSV Dataframe R into Your Workflow
The transition from raw CSV files to a structured dataframe in R is a critical step for any data-driven professional. Whether you're processing transaction logs, survey responses, or scientific measurements, the ability to bring CSV dataframe R into your analysis pipeline determines the efficiency of your workflow. The process isn’t just about reading a file—it’s about transforming unstructured data into a format where statistical operations, machine learning models, and visualizations can thrive.
Yet, many practitioners underestimate the nuances of this conversion. A poorly imported dataset can cascade into errors—missing values misinterpreted as zeros, categorical variables treated as numeric, or encoding issues corrupting text fields. These pitfalls often stem from overlooking R’s built-in functions like read.csv() or fread(), which offer more than basic file reading. They provide tools to handle delimiters, skip headers, or enforce data types—features that can save hours of debugging later.
The stakes are higher in collaborative environments where datasets evolve. A script that flawlessly brings CSV dataframe R into one project may fail when applied to another due to differing column structures or encoding schemes. This is why understanding the underlying mechanics—from memory allocation to lazy evaluation—becomes non-negotiable. The goal isn’t just to import data; it’s to do so predictably, scalably, and with minimal overhead.

The Complete Overview of Bringing CSV Dataframe R into Analysis
The foundation of working with CSV data in R lies in the interplay between file formats and programming paradigms. CSV (Comma-Separated Values) files are ubiquitous because they strike a balance between human readability and machine processability. However, their simplicity masks complexities: missing values represented as empty cells, inconsistent delimiters (tabs, semicolons), or embedded commas within quoted text. R’s ecosystem addresses these challenges through specialized packages and functions designed to parse CSV data into dataframes—a tabular structure optimized for analysis.
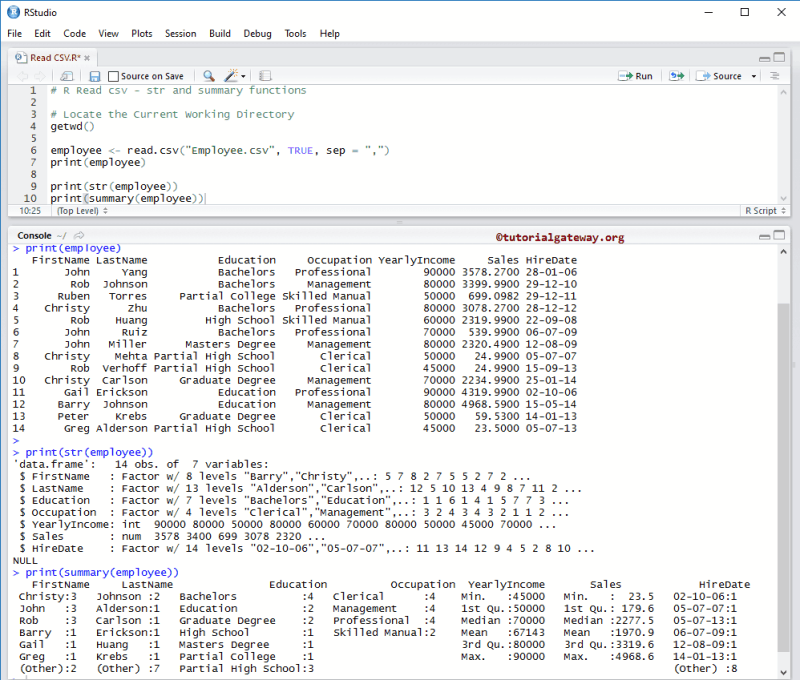
At its core, the process of bringing CSV dataframe R involves three phases: file ingestion, data validation, and transformation. The ingestion phase uses functions like read.csv() from base R or read_csv() from the readr package, which differ in speed and memory efficiency. Validation checks for structural integrity—verifying column types, detecting NA values, and ensuring no rows are truncated. Transformation then reshapes the data to fit analytical needs, whether through filtering, aggregation, or type conversion.
Historical Background and Evolution
The relationship between CSV and R dates back to the early 2000s, when R gained traction as a statistical computing tool. Early versions relied on base R’s read.table(), a function originally designed for more general text parsing. As datasets grew larger and more complex, limitations became apparent: slow performance on files exceeding 1MB, rigid handling of delimiters, and no built-in support for modern encodings like UTF-8. This gap spurred the development of alternatives, most notably the data.table package’s fread(), which introduced lazy evaluation and multithreading to accelerate imports.
Table of Contents
- The Complete Overview of Bringing CSV Dataframe R into Analysis
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does read.csv() sometimes fail to read large files, while fread() succeeds?
- Q: How can I handle CSV files with irregular delimiters (e.g., tabs or pipes) in R?
- Q: What’s the best way to preserve column data types when importing a CSV into R?
- Q: Can I import a CSV with embedded commas (e.g., "New York, NY") without errors?
- Q: How do I skip specific rows (e.g., headers or footnotes) when importing a CSV?
- Q: What should I do if my CSV has mixed line endings (CRLF/LF) causing parsing errors?
- Q: Is there a way to preview a CSV’s structure before importing it entirely into R?
- Q: How can I handle CSV files with different decimal separators (e.g., commas in European formats)?
- Q: What’s the most memory-efficient way to import a 1GB CSV in R?
The readr package, introduced in 2015 as part of the tidyverse, marked a paradigm shift. It abandoned R’s traditional S3 object system in favor of a faster, columnar approach inspired by modern data processing frameworks. Functions like read_csv() and read_csv2() (for semicolon-delimited files) became industry standards for their speed and robustness. Meanwhile, packages like readxl extended support to Excel files, blurring the line between CSV and spreadsheet data. Today, the choice of method depends on context: readr for speed, data.table for memory efficiency, and base R for simplicity.
Core Mechanisms: How It Works
The mechanics of bringing CSV dataframe R hinge on two critical operations: parsing and memory allocation. Parsing involves breaking down the CSV’s text into tokens—identifying delimiters, handling quoted fields, and converting strings to appropriate data types (e.g., dates, integers). R’s readr package optimizes this by processing data column-by-column rather than row-by-row, reducing overhead. In contrast, read.csv() reads the entire file into memory before parsing, which can be problematic for large datasets.
Memory allocation is where performance diverges most sharply. The data.table::fread() function, for instance, uses lazy evaluation to defer processing until explicitly called, making it ideal for datasets too large to fit in RAM. It also supports chunked reading, where files are processed in segments to avoid crashes. Meanwhile, readr leverages C++ backend optimizations to minimize garbage collection pauses. Understanding these trade-offs is essential: a script that works for a 100KB CSV may fail on a 100MB file without adjustments to memory limits or chunk sizes.
Key Benefits and Crucial Impact
The ability to efficiently bring CSV dataframe R into an analysis pipeline is more than a technical convenience—it’s a competitive advantage. For researchers, it accelerates hypothesis testing by reducing data cleaning time. For data engineers, it ensures reproducibility by standardizing input formats. Even in business intelligence, where CSV exports from ERP systems are common, the speed of ingestion can determine whether insights are delivered daily or weekly.
Beyond speed, the impact lies in flexibility. R’s ecosystem allows for custom parsing logic—handling irregular delimiters, multi-line fields, or embedded metadata. This adaptability is critical in domains like genomics or finance, where datasets defy conventional structures. The ripple effects extend to downstream tasks: a well-imported dataframe simplifies joins, aggregations, and visualizations, while poor imports introduce errors that propagate through entire analyses.
— Hadley Wickham, Creator of the tidyverse
"CSV is the lingua franca of data exchange, but its simplicity belies the complexity of parsing it correctly. The tools in R aren’t just about reading files—they’re about preserving the integrity of the data’s meaning."
Major Advantages
- Performance Optimization: Functions like
fread()andread_csv()are engineered to handle large files with minimal memory overhead, often processing 100MB+ files in seconds. - Data Type Preservation: Modern parsers automatically infer column types (e.g., dates, factors) and handle edge cases like scientific notation or locale-specific number formats.
- Error Handling: Built-in validation flags issues like malformed rows or encoding mismatches, reducing debugging time during analysis.
- Integration with Pipelines: Packages like
readranddata.tableintegrate seamlessly withdplyrandmagrittr, enabling end-to-end workflows from ingestion to visualization. - Scalability: Lazy evaluation and chunked reading allow processing datasets larger than available RAM, a necessity in big data environments.

Comparative Analysis
| Function/Method | Key Strengths and Weaknesses |
|---|---|
base::read.csv() |
Pros: Simple syntax, no dependencies. Cons: Slow for large files (>1MB), limited type inference, memory-intensive. |
readr::read_csv() |
Pros: Fast (C++ backend), columnar parsing, handles UTF-8. Cons: Requires |
data.table::fread() |
Pros: Blazing fast, lazy evaluation, chunked reading. Cons: Steeper learning curve, memory management required for very large datasets. |
readxl::read_excel() |
Pros: Supports Excel files, preserves formatting. Cons: Overkill for CSV, slower than specialized parsers. |
Future Trends and Innovations
The evolution of bringing CSV dataframe R is increasingly tied to broader trends in data infrastructure. Cloud-native tools like arrow and duckdb are enabling in-memory processing of datasets that once required distributed systems. R’s integration with these technologies—via packages like arrow’s read_parquet()—suggests a future where CSV remains the interchange format, but parsing happens in optimized backends.
Another frontier is automated data profiling. Tools like skimr or profilr can now analyze CSV structures before import, suggesting optimal parsing parameters. Machine learning is also playing a role: models trained on millions of CSV files can predict likely delimiters or encodings, reducing manual configuration. As R continues to bridge statistical rigor with modern data engineering, the act of importing a CSV will become less about syntax and more about leveraging contextual intelligence.
Conclusion
The process of bringing CSV dataframe R into an analysis workflow is deceptively simple on the surface but deeply technical beneath. It’s not just about executing a function—it’s about understanding the trade-offs between speed, memory, and flexibility. The right choice depends on the dataset’s size, structure, and the analysis’s requirements. For small, well-formed CSVs, base R’s read.csv() suffices. For large or irregular files, fread() or read_csv() offer superior performance and control.
As data grows more voluminous and complex, the tools for importing CSV files in R will continue to evolve. The key for practitioners is to stay informed about these advancements while maintaining a pragmatic approach: focus on reproducibility, validate assumptions, and choose methods that align with the project’s scale. Mastery here isn’t about memorizing functions—it’s about designing workflows that turn raw data into actionable insights, reliably and efficiently.
Comprehensive FAQs
Q: Why does read.csv() sometimes fail to read large files, while fread() succeeds?
A: read.csv() loads the entire file into memory before parsing, which can cause crashes with files exceeding available RAM. fread() uses lazy evaluation and chunked reading, processing data in segments to avoid memory overload. For files >100MB, fread() or read_csv() with col_types specified is recommended.
Q: How can I handle CSV files with irregular delimiters (e.g., tabs or pipes) in R?
A: Use the sep argument in read.csv() or readr::read_delim(). For mixed delimiters, preprocess the file with gsub() or use readr::read_csv2() for semicolon-separated files. The data.table::fread() function also supports custom delimiters via sep = "|" or sep = "\t".
Q: What’s the best way to preserve column data types when importing a CSV into R?
A: Use readr::read_csv() with explicit col_types or col_select() to enforce types. For example, col_types = cols(date = col_date(), numeric = col_double()) ensures dates and numbers are parsed correctly. Alternatively, data.table::fread() with data.table = FALSE and colClasses achieves similar control.
Q: Can I import a CSV with embedded commas (e.g., "New York, NY") without errors?
A: Yes, by ensuring the field is quoted in the CSV. R’s parsers (including read.csv()) automatically handle quoted fields containing delimiters. If the CSV lacks quotes, preprocess it with gsub() or use readr::read_csv(), which is more forgiving with malformed rows. For extreme cases, consider read.fwf() (fixed-width parsing).
Q: How do I skip specific rows (e.g., headers or footnotes) when importing a CSV?
A: Use the skip argument in read.csv() or readr::read_csv(skip = 2) to skip the first two rows. For dynamic skipping (e.g., based on content), combine with read_lines() to inspect rows before parsing. data.table::fread() supports skip and select for row/column filtering.
Q: What should I do if my CSV has mixed line endings (CRLF/LF) causing parsing errors?
A: Normalize line endings before import using gsub("\r\n", "\n", text) or gsub("\r", "\n", text). Alternatively, use readr::read_csv(), which handles mixed line endings gracefully. For large files, preprocess with readLines() and writeLines() to standardize formatting.
Q: Is there a way to preview a CSV’s structure before importing it entirely into R?
A: Yes, use readr::read_lines() to inspect the first 10–20 rows or data.table::fread(..., nrows = 5) to sample data. For metadata, the skimr::skim() function provides a summary after partial import. Tools like arrow::read_csv() also support lazy previewing.
Q: How can I handle CSV files with different decimal separators (e.g., commas in European formats)?
A: Specify the locale in readr::read_csv() with locale = locale(decimal_mark = ","). For base R, use read.csv(..., dec = ","). The data.table::fread() function requires fill = TRUE and manual type conversion if decimals are misparsed.
Q: What’s the most memory-efficient way to import a 1GB CSV in R?
A: Use data.table::fread() with chunked reading (nrows = 1e6) or arrow::read_csv(), which leverages columnar storage. For base R, read.csv(..., nrows = 1e5) in a loop with rbindlist() (from data.table) can work, but fread() is preferred for scalability.
Q: Can I import a CSV and simultaneously apply transformations (e.g., filtering rows)?h3>
A: Yes, chain parsing with dplyr or data.table. Example: library(dplyr); read_csv("file.csv") %>% filter(column > 10). For data.table, fread("file.csv")[, column > 10] applies transformations during import. This reduces memory usage by filtering before full loading.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.