How to Scrape Google Flights: The Hidden Strategy for Real-Time Airfare Data
Google Flights doesn’t just show prices—it aggregates global demand, hidden carrier fees, and dynamic pricing algorithms that most travelers never see. Behind its polished interface lies a treasure trove of structured data: route popularity, seasonal trends, and even competitor pricing that could save businesses or frequent flyers thousands annually. But extracting this data legally and efficiently requires more than a simple copy-paste. The process of scraping Google Flights—whether for personal use, market research, or building travel tech—demands precision, awareness of anti-scraping measures, and an understanding of how Google’s systems detect and block automated requests.
The challenge isn’t just technical; it’s strategic. Google’s infrastructure is designed to prioritize user experience over raw data accessibility, meaning traditional scraping tools often trigger CAPTCHAs, IP bans, or throttled responses within minutes. Yet, the data remains invaluable: airlines, travel agencies, and even budget-conscious globetrotters rely on this information to outmaneuver competitors or secure deals before they vanish. The key lies in mimicking human-like interactions while respecting Google’s policies—a balance that separates effective data extraction from outright violation.
This guide cuts through the noise. We’ll dissect the anatomy of Google Flights’ data structure, explore both automated and manual extraction methods, and weigh the legal gray areas against the tangible benefits. Whether you’re a data analyst, a startup founder, or a savvy traveler, the insights here will redefine how you approach scraping Google Flights—without getting flagged.
The Complete Overview of Scraping Google Flights
Google Flights operates as a dynamic aggregator, pulling real-time data from hundreds of airlines, booking platforms, and internal algorithms to generate search results. When you query a route—say, New York to Tokyo in June—the system doesn’t just fetch static prices. It factors in fuel surcharges, seat availability, historical booking patterns, and even competitor promotions from Expedia or Kayak. This complexity makes scraping Google Flights a multi-layered puzzle: the data isn’t stored in a single API endpoint but is assembled client-side via JavaScript, cached dynamically, and often obfuscated to prevent bulk extraction.The core appeal of scraping Google Flights lies in its granularity. Unlike third-party APIs (which often charge per request or lack depth), Google’s platform offers unfiltered access to:
The catch? Google’s infrastructure is built to deter scraping. Every request triggers a series of checks: IP reputation, user-agent fingerprinting, and behavioral analysis (e.g., rapid-fire searches without mouse movements). Bypassing these requires more than brute-force automation—it demands an understanding of how Google’s systems classify "legitimate" vs. "bot" traffic.
Historical Background and Evolution
Google Flights launched in 2011 as part of Google’s broader push into travel tech, a sector dominated by legacy players like Expedia and Orbitz. Initially, the platform relied on partnerships with airlines and OTA (Online Travel Agency) feeds, but its real innovation came in 2016 with the introduction of dynamic pricing algorithms that predicted fare drops based on historical data. This shift marked the beginning of Google’s move toward becoming a data-driven travel intermediary rather than just a search tool.Table of Contents
- The Complete Overview of Scraping Google Flights
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Is scraping Google Flights legal?
- Q: What tools are best for scraping Google Flights?
- Q: How do I avoid getting blocked while scraping?
- Q: Can I scrape Google Flights data for resale?
- Q: Are there alternatives to scraping Google Flights?
- Q: How can I analyze scraped flight data effectively?
The evolution of scraping Google Flights mirrors the arms race between data extractors and platform defenders. Early adopters in the 2010s used simple Python scripts with `requests` libraries to pull HTML tables of flight results. By 2018, Google had rolled out CAPTCHA challenges for suspicious activity, forcing scrapers to adopt headless browsers (like Puppeteer or Selenium) to render JavaScript-heavy pages. Today, the most sophisticated methods involve:
The stakes have risen further with Google’s integration of Google Travel, which now blends flights, hotels, and activities into a single data stream. Scraping this unified ecosystem requires parsing nested JSON responses and handling multi-step user flows (e.g., filtering by cabin class or loyalty programs).
Core Mechanisms: How It Works
At its core, scraping Google Flights hinges on intercepting and parsing the data Google sends to your browser. When you load a search results page, the platform dynamically fetches data via XHR (XMLHttpRequest) calls to endpoints like:```
https://www.google.com/travel/flights/search/results
```
These endpoints return JSON payloads containing flight details, prices, and metadata. The challenge is that Google doesn’t expose a public API for this data—it’s designed for human consumption, not programmatic access.
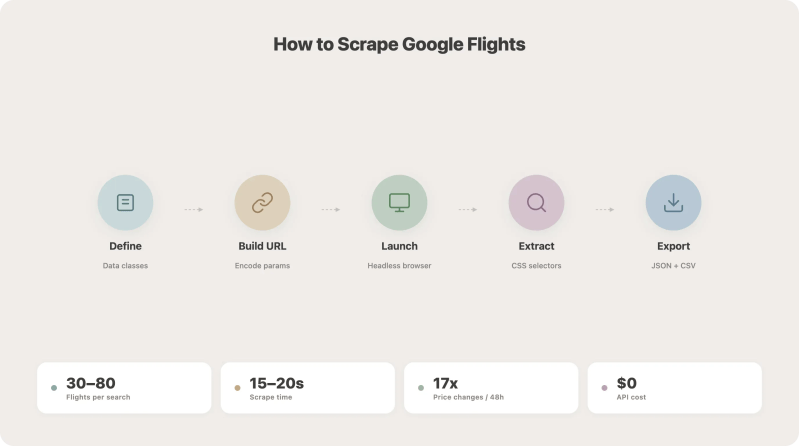
To extract this data, you’ll need to:
1. Reverse-engineer the request payload: Google’s frontend sends a POST request with parameters like `origin`, `destination`, `date`, and `tripType`. Replicating this payload with the correct headers (e.g., `Accept: application/json`) is the first step.
2. Handle authentication: Some endpoints require a session cookie (e.g., `SID` or `APISID`) to return full data. Obtaining these legally involves logging in via a browser session.
3. Process the response: The JSON response includes nested objects for flights, airlines, and pricing. Tools like `BeautifulSoup` (for HTML) or `jsonpath` (for JSON) help extract structured data.
For example, a typical flight result snippet in the response might look like:
```json
{
"flight": {
"id": "12345",
"departure": {
"airport": "JFK",
"time": "14:30",
"airline": {
"name": "Delta",
"code": "DL"
}
},
"price": {
"total": 499.99,
"base": 399.99,
"taxes": 100.00,
"currency": "USD"
}
}
}
```
The deeper you go, the more you’ll encounter rate-limiting and data obfuscation. Google may return truncated responses or redirect to a CAPTCHA page if it detects automated traffic. This is where tools like Scrapy with middleware or Playwright (for browser automation) become essential.
Key Benefits and Crucial Impact
The ability to scrape Google Flights isn’t just a technical feat—it’s a competitive advantage. Airlines and OTAs use this data to optimize dynamic pricing, while travel agencies leverage it to undercut competitors. For individuals, the insights can mean saving hundreds on a single ticket by identifying the best time to book or the most flexible fare options. The impact extends beyond pricing: understanding demand trends helps businesses forecast inventory, and analyzing competitor parity reveals gaps in service offerings.Yet, the benefits come with caveats. Google’s Terms of Service prohibit scraping without permission, and aggressive extraction can lead to legal action or IP bans. The ethical dilemma is real: is this data extraction for personal gain, or is it part of a larger ecosystem that benefits travelers? The answer often lies in the method—using scraped data to improve transparency (e.g., building a fare-comparison tool) vs. exploiting it for arbitrage.
"The most valuable data isn’t the price itself—it’s the pattern behind the price. Scraping Google Flights reveals when airlines drop fares, how competitors react, and which routes are artificially inflated. That’s the difference between a one-time discount and a sustainable business strategy."
— Travel Data Analyst, Skytrax Research
Major Advantages
- Real-time pricing intelligence: Track fare drops within minutes of an airline’s update, allowing you to book before competitors or resell at a premium.
- Competitor benchmarking: Compare Google’s prices against Expedia, Kayak, or direct airline sites to identify arbitrage opportunities or pricing inconsistencies.
- Demand forecasting: Analyze historical data to predict peak/off-peak seasons for specific routes, helping businesses adjust inventory or marketing spend.
- Hidden fee exposure: Extract and compare taxes, baggage fees, and surcharges across airlines to find the most transparent (or exploitative) carriers.
- Automated alerts: Build systems to notify you when a desired route hits a target price, eliminating manual monitoring.

Comparative Analysis
Not all methods of scraping Google Flights are equal. Below is a comparison of the most common approaches, balancing effectiveness, legality, and technical complexity.| Method | Pros and Cons |
|---|---|
| Manual Data Entry |
|
| Python + Requests Library |
|
| Selenium/Puppeteer |
|
| Third-Party APIs (e.g., Skyscanner, Amadeus) |
|
Future Trends and Innovations
The next frontier in scraping Google Flights lies in AI-driven extraction and predictive analytics. Current methods rely on rule-based scraping, but emerging tools like Optical Character Recognition (OCR) for CAPTCHAs and machine learning models to predict Google’s rate-limiting patterns could automate the process further. Additionally, Google’s shift toward graph-based data structures (e.g., linking flights to hotels and activities) will require scrapers to adopt graph databases like Neo4j to map relationships between travel components.Another trend is the rise of legal data partnerships. While Google doesn’t offer a public API for Flights data, companies like ForwardKeys or IATA’s BSP provide licensed alternatives. The future may see Google offering tiered access to its data—either through paid APIs or white-labeled tools for travel businesses—reducing the need for scraping entirely.

Conclusion
Scraping Google Flights is a high-stakes game of cat and mouse, where the rewards—data-driven pricing, competitive insights, and cost savings—are matched only by the risks of detection and legal repercussions. The key to success lies in balancing automation with stealth: using tools like Playwright or Scrapy with proxy rotation, while staying within the ethical and legal boundaries. For individuals, the insights can be personally transformative; for businesses, they’re a strategic imperative.The landscape will continue to evolve, with Google tightening its defenses and scrapers adapting with AI and proxy networks. One thing is certain: the data remains too valuable to ignore. Whether you’re a data scientist, a travel startup, or a frequent flyer, understanding how to scrape Google Flights—responsibly—puts you ahead of the curve.
Comprehensive FAQs
Q: Is scraping Google Flights legal?
Legally, Google’s Terms of Service prohibit scraping without permission. However, many argue that extracting publicly visible data (like prices) falls under "fair use." The risk lies in the scale and method: small-scale scraping for personal use is less likely to trigger action than bulk extraction for resale. Always review Google’s Developer Policies and consider using official APIs where possible.
Q: What tools are best for scraping Google Flights?
For JavaScript-heavy pages, Playwright or Puppeteer are ideal due to their browser automation capabilities. For large-scale extraction, Scrapy with middleware (e.g., `scrapy-playwright`) is efficient. Lightweight tasks can use Python + Requests, but expect CAPTCHAs quickly. Tools like Bright Data or Smartproxy help with IP rotation and anti-detection.
Q: How do I avoid getting blocked while scraping?
Blocking requires a multi-layered approach:
- Use rotating proxies (residential IPs are best).
- Randomize user-agent strings and request delays (3–10 seconds between actions).
- Emulate human behavior with mouse movements and scrolling (Puppeteer’s `mouse` API helps).
- Avoid session fixation—log in via a fresh browser session for each scrape.
- Monitor CAPTCHA triggers and adjust delays accordingly.
Q: Can I scrape Google Flights data for resale?
Reselling scraped data from Google Flights is a legal gray area. Google’s ToS explicitly prohibit "repackaging" or "redistributing" its content without permission. If you’re building a tool (e.g., a fare-comparison site), consider partnering with Google’s Travel Ads API instead. For personal use, the risks are lower, but commercial exploitation could lead to cease-and-desist letters or DMCA takedowns.
Q: Are there alternatives to scraping Google Flights?
Yes. If scraping isn’t viable, consider:
- Google’s unofficial APIs: Communities like GitHub host reverse-engineered endpoints (use at your own risk).
- Third-party APIs: Skyscanner, Amadeus, or Sabre offer flight data with legal guarantees.
- Webhooks/Alerts: Services like Hopper or Google Flights’ own price alerts (limited to personal use).
- Public datasets: Some airlines (e.g., Southwest) release partial data, but coverage is sparse.
Q: How can I analyze scraped flight data effectively?
Raw scraped data is useless without processing. Use:
- Python libraries: `pandas` for cleaning, `matplotlib/seaborn` for visualizing trends.
- Time-series analysis: Track price changes over days/weeks to identify patterns.
- Competitor comparison: Merge scraped data with other OTAs to find pricing anomalies.
- Machine learning: Train models to predict fare drops using historical data (e.g., with `scikit-learn`).
- Dashboards**: Tools like Tableau or Power BI can turn data into actionable insights.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.