Data-Driven Testing: The Definitive Testing Comprehensive Guide
Data-driven testing isn’t just a buzzword—it’s a paradigm shift in how organizations validate software. By replacing intuition with structured metrics, teams now measure test coverage, defect rates, and risk exposure with surgical precision. The result? Fewer critical bugs slipping through, faster release cycles, and a measurable ROI on QA investments.
Yet despite its advantages, many teams still rely on outdated scripts or manual processes, missing the full potential of testing comprehensive guide data driven methodologies. The gap between theoretical frameworks and practical implementation remains a hurdle, especially in industries where compliance and reliability are non-negotiable—think fintech, healthcare, or aerospace. The question isn’t whether data-driven testing works; it’s how to deploy it without overcomplicating workflows or sacrificing agility.
This guide cuts through the noise, blending technical rigor with actionable insights. We’ll dissect the mechanics behind data-driven validation, compare it to traditional approaches, and examine how emerging technologies—like generative AI and real-time analytics—are reshaping the field. Whether you’re a QA lead, developer, or stakeholder, the goal is clear: equip you with the knowledge to implement testing comprehensive guide data driven strategies that align with your organization’s scale and goals.

The Complete Overview of Data-Driven Testing
At its core, testing comprehensive guide data driven refers to a methodology where test cases, scenarios, and even test environments are dynamically generated or selected based on real-time or historical data. Unlike scripted testing—where inputs are hardcoded—this approach treats data as a first-class citizen, feeding it into test engines to simulate edge cases, validate performance under load, or stress-test APIs with millions of permutations. The key differentiator? Tests aren’t just executed; they’re informed by data patterns, user behavior, or system telemetry.
This isn’t a one-size-fits-all solution. For example, a retail platform might use purchase history data to generate synthetic test transactions, while a SaaS company could leverage API call logs to identify high-risk endpoints for fuzz testing. The flexibility lies in how data is sourced—whether from databases, logs, third-party feeds, or even synthetic generation tools. What unites these use cases is the principle: tests should reflect the real world, not an abstracted ideal.
Historical Background and Evolution
The roots of testing comprehensive guide data driven trace back to the 1990s, when early performance testing tools like LoadRunner began using statistical models to simulate user loads. However, the term "data-driven testing" gained traction in the 2000s as agile methodologies demanded faster, more adaptive QA processes. Frameworks like FitNesse and Selenium’s data-driven extensions allowed testers to decouple test logic from input data, enabling reusable scripts with dynamic payloads.
Table of Contents
- The Complete Overview of Data-Driven Testing
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I get started with data-driven testing if my team has no automation experience?
- Q: What types of data should I use for testing?
- Q: How do I measure the success of a data-driven testing initiative?
- Q: Can data-driven testing replace manual testing entirely?
- Q: What are the biggest challenges in implementing data-driven testing?
- Q: How does data-driven testing fit into CI/CD pipelines?
Today, the evolution is being accelerated by three forces: the explosion of big data, the rise of DevOps, and advancements in automation. Tools like Postman, JMeter, and custom Python scripts now integrate with data lakes, enabling teams to run tests against petabytes of historical or synthetic data. Meanwhile, AI-driven test generation—where models like GitHub Copilot or custom LLMs propose test cases based on code changes—is blurring the line between human and machine-driven validation.
Core Mechanisms: How It Works
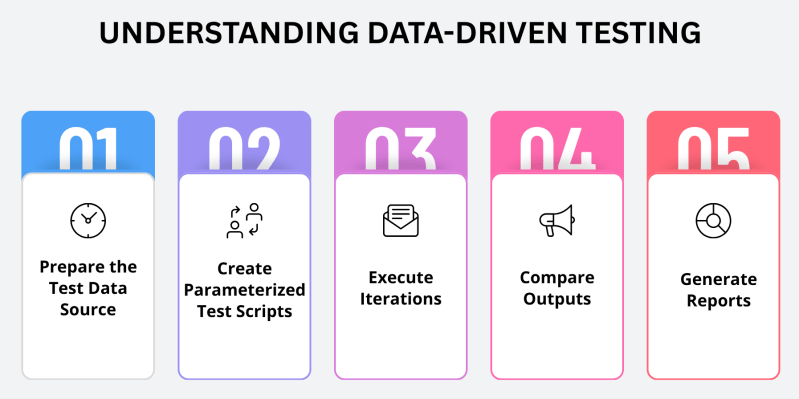
The mechanics of testing comprehensive guide data driven revolve around three layers: data ingestion, test orchestration, and result analysis. First, data is collected from diverse sources—user interaction logs, sensor feeds, or even crowdsourced datasets—and stored in a structured format (e.g., JSON, CSV, or a dedicated test data repository). This data is then processed to identify patterns, outliers, or critical paths that warrant testing. For instance, a banking app might prioritize test cases tied to high-value transactions or failed authentication attempts.
Next, test frameworks ingest this data to generate or parameterize test cases. Tools like Robot Framework or Cypress can dynamically feed variables into scripts, while performance tools like Locust use data to simulate complex user journeys. The final layer involves analyzing test outcomes against predefined metrics—such as pass/fail rates, execution time, or resource utilization—to identify trends or anomalies. This feedback loop ensures that future tests are refined based on empirical evidence, not assumptions.
Key Benefits and Crucial Impact
Organizations adopting testing comprehensive guide data driven methodologies report a 30–50% reduction in manual testing effort, according to industry benchmarks from Accenture and Capgemini. The impact extends beyond efficiency: by aligning tests with real-world data, teams can proactively address issues like latency spikes, security vulnerabilities, or compliance gaps before they escalate. For example, a healthcare provider might use patient data to simulate EHR system loads during peak hours, ensuring HIPAA compliance under stress.
The psychological shift is equally significant. Data-driven testing demystifies QA by replacing subjective judgments with quantifiable insights. When stakeholders see test coverage metrics tied to business risks (e.g., "92% of high-value API endpoints are validated"), the conversation shifts from "Is the software good enough?" to "What specific risks remain unmitigated?" This transparency is critical in regulated industries where accountability is paramount.
"Data-driven testing isn’t about replacing humans—it’s about giving them the right questions to ask. The best testers don’t just run scripts; they interpret data to ask, 'What haven’t we tested yet?'"
— James Bach, Context-Driven Testing Pioneer
Major Advantages
- Scalability: Automated data ingestion allows tests to scale horizontally—imagine running 10,000 API calls against a dataset of 1 million user profiles without manual intervention.
- Risk-Based Prioritization: Tests focus on high-impact scenarios (e.g., payment failures, system crashes) by analyzing historical defect patterns.
- Reduced Redundancy: Shared test data repositories eliminate duplicate efforts across teams, improving collaboration.
- Real-Time Feedback: Integration with CI/CD pipelines enables immediate test execution post-code commit, catching regressions faster.
- Compliance Readiness: Audit trails of test data and outcomes simplify regulatory reporting (e.g., ISO 27001, GDPR).
Comparative Analysis
| Traditional Scripted Testing | Data-Driven Testing |
|---|---|
| Test cases are static; inputs are hardcoded. | Test cases are dynamic; inputs are data-fed. |
| High maintenance—updates require script rewrites. | Low maintenance—data changes drive test updates. |
| Limited to predefined scenarios. | Covers edge cases via statistical sampling. |
| Manual effort scales poorly with complexity. | Automation handles scale via data pipelines. |
Future Trends and Innovations
The next frontier for testing comprehensive guide data driven lies in AI augmentation. Generative models are now capable of creating synthetic test data that mimics real-world distributions—critical for privacy-sensitive domains like biotech or fintech. For instance, tools like Diffblue or Testim use ML to auto-generate unit tests from code, while larger language models (LLMs) can draft test scenarios based on natural language requirements. The challenge will be balancing automation with human oversight to avoid "hallucinated" test cases that miss edge cases.
Another trend is the convergence of testing with observability. Modern applications—especially microservices—require tests to be context-aware, pulling data from distributed logs, metrics, and traces (e.g., OpenTelemetry). This "test-as-code" approach, combined with real-time analytics, will enable predictive testing: identifying potential failures before they occur by analyzing system telemetry. The goal? Moving from reactive QA to proactive risk management.

Conclusion
Data-driven testing isn’t a silver bullet, but it’s the closest thing modern QA has to one. The shift from guesswork to evidence-based validation reduces costs, improves quality, and aligns testing with business objectives. The key to success lies in integration—seamlessly embedding data sources into existing workflows without disrupting agility. Start small: pilot with high-risk components, then scale based on measurable outcomes.
As the field evolves, the divide between "data-driven" and "traditional" testing will blur entirely. The future belongs to organizations that treat testing as a data science problem—not just a checkbox in the release process. For those willing to embrace the shift, the rewards are clear: fewer outages, happier users, and a competitive edge in an era where failure isn’t an option.
Comprehensive FAQs
Q: How do I get started with data-driven testing if my team has no automation experience?
A: Begin with low-code tools like Postman or SoapUI, which offer built-in data-driven features. Start by parameterizing existing manual test cases with CSV/JSON inputs. For example, replace hardcoded login credentials with a dataset of valid/invalid pairs. Gradually introduce scripting (Python/JavaScript) to handle complex data transformations. Partner with a DevOps engineer to set up a simple CI pipeline (e.g., GitHub Actions) to automate test execution.
Q: What types of data should I use for testing?
A: Prioritize data that reflects real-world usage patterns. For APIs, use production logs or synthetic data mimicking request/response cycles. For UI testing, capture user session recordings (via tools like Hotjar) or generate data based on persona profiles (e.g., "power users" vs. "occasional buyers"). Avoid using only "happy path" data—include outliers (e.g., malformed inputs, extreme values) to stress-test robustness. Always anonymize sensitive data to comply with privacy laws.
Q: How do I measure the success of a data-driven testing initiative?
A: Track three key metrics:
- Defect Detection Rate: Compare the number of critical bugs caught pre-release vs. post-release.
- Test Coverage Efficiency: Measure the % of high-risk scenarios covered by automated tests (e.g., "90% of payment flows are validated").
- Time-to-Resolution: Reduce the average time to fix a bug by correlating test data with incident reports.
Q: Can data-driven testing replace manual testing entirely?
A: No. While automation excels at repetitive, data-heavy tasks, manual testing remains essential for exploratory scenarios (e.g., usability, ad-hoc investigations) and contexts requiring human judgment (e.g., evaluating UI/UX nuances). The optimal approach is a hybrid model: use data-driven tests for coverage and regression, and reserve manual testing for edge cases or creative problem-solving. Tools like Applitools (for visual testing) bridge this gap by combining AI with human oversight.
Q: What are the biggest challenges in implementing data-driven testing?
A:
- Data Quality: Garbage in, garbage out. Poor or biased datasets lead to misleading test outcomes. Invest in data validation pipelines (e.g., Great Expectations).
- Toolchain Fragmentation: Integrating disparate tools (e.g., JIRA for test management, BigQuery for data storage) requires API-driven workflows or middleware.
- Skill Gaps: Teams often lack expertise in data engineering or test automation. Upskill via platforms like Udacity’s "Software Tester" course or certifications from ISTQB.
- Cultural Resistance: Some testers fear automation will make their roles obsolete. Frame the transition as "augmentation" (e.g., "You’ll spend less time on repetitive tasks and more on high-impact analysis").
Q: How does data-driven testing fit into CI/CD pipelines?
A: Integrate data-driven tests at the build (unit/integration tests), deploy (smoke tests), and release (performance/load tests) stages. For example:
- Use a Git hook to trigger tests when new data is committed to a repository.
- Deploy tests as microservices (e.g., via Kubernetes) to scale dynamically with pipeline load.
- Leverage feature flags to toggle test data sets based on environment (e.g., "prod-like" data in staging).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.