How to Select the Optimal Storage for Databases Choosing Best Storage Solution
The wrong storage choice can cripple a database. A high-latency disk array may turn a real-time analytics engine into a sluggish bottleneck, while over-provisioned SSDs inflate costs without tangible gains. The stakes are higher than ever: modern applications demand sub-millisecond response times, petabyte-scale storage, and seamless scalability—all while balancing budget constraints. Yet, most organizations still treat storage selection as an afterthought, defaulting to legacy systems or generic cloud tiers without evaluating workload-specific needs. The result? Underperforming queries, unnecessary expenses, and missed opportunities for innovation.
Databases choosing best storage solution isn’t just about capacity—it’s about aligning storage characteristics with the database’s operational patterns. A transactional OLTP system thrives on low-latency, high-durability storage, while a data lake optimized for batch processing can tolerate higher latency if it delivers cost-effective sequential reads. The disconnect often stems from siloed decision-making: database administrators focus on query optimization, while storage teams prioritize vendor SLAs without considering how disks interact with transaction logs or index structures. This misalignment leads to inefficiencies that compound as data volumes grow.
The solution lies in a systematic approach that evaluates storage from three dimensions: performance metrics (IOPS, throughput, latency), cost structures (per-GB pricing, operational overhead), and architectural compatibility (file system support, RAID configurations, caching layers). Whether deploying PostgreSQL on bare-metal NVMe drives or migrating a MongoDB cluster to object storage, the optimal choice depends on a granular understanding of how storage hardware translates into database behavior. This guide dissects the trade-offs, historical context, and emerging trends shaping databases choosing best storage solution in 2024 and beyond.
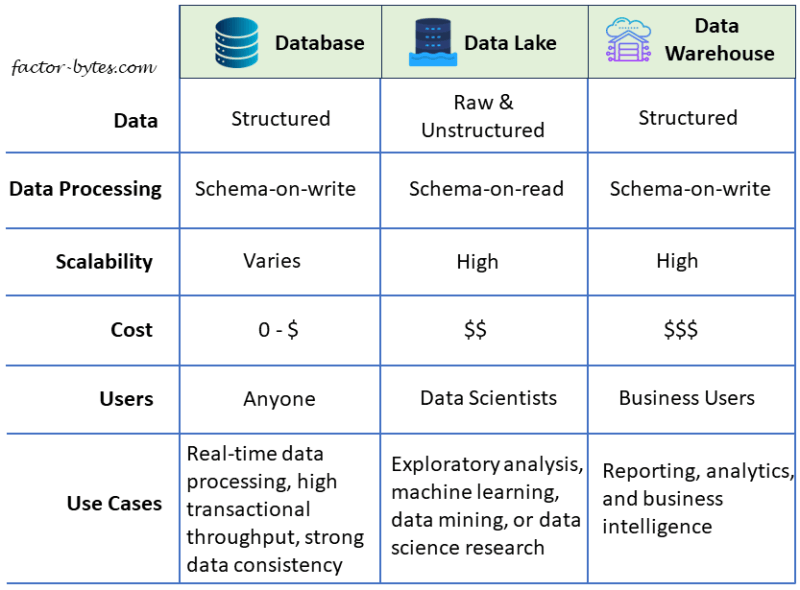
The Complete Overview of Databases Choosing Best Storage Solution
At its core, databases choosing best storage solution revolves around matching persistence layers to the database’s access patterns, durability requirements, and scalability needs. The decision isn’t static—it evolves as workloads shift from read-heavy to write-heavy, or as compliance mandates impose stricter retention policies. For example, a financial ledger database prioritizes synchronous writes to ensure ACID compliance, while a social media feed prioritizes low-latency reads to serve personalized content. The storage layer must support these divergent needs without becoming a single point of failure.
The landscape has fragmented into specialized storage tiers, each excelling in specific scenarios. Traditional HDDs remain cost-effective for cold data, while SSDs and NVMe drives dominate hot datasets requiring sub-millisecond access. Cloud providers have introduced hybrid models like Amazon S3 + EBS, blending object storage’s scalability with block storage’s performance. Meanwhile, emerging technologies—such as persistent memory (PMem) and storage-class memory (SCM)—blur the line between RAM and disk, offering byte-addressable storage with near-DRAM speeds. Navigating this ecosystem requires a taxonomy of storage types, their trade-offs, and how they integrate with database engines.
Historical Background and Evolution
The evolution of databases choosing best storage solution mirrors the broader trajectory of computing hardware. In the 1970s, databases like IBM’s IMS relied on drum storage and magnetic tape, where access times measured in seconds. The advent of RAID arrays in the 1980s introduced redundancy and parallelism, enabling relational databases (e.g., Oracle, DB2) to handle transactional workloads. By the 1990s, the rise of SANs (Storage Area Networks) decoupled storage from servers, allowing dynamic scaling—but at the cost of complexity and latency.
Table of Contents
- The Complete Overview of Databases Choosing Best Storage Solution
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I determine if my database’s storage is a bottleneck?
- Q: Should I use SSDs for all database workloads?
- Q: How does RAID configuration affect database performance?
- Q: Can I mix storage types in a single database cluster?
- Q: What are the risks of using cloud object storage for a database?
- Q: How do I future-proof my database storage?
The 2000s marked a turning point with the proliferation of SSDs, which reduced seek times from milliseconds to microseconds, directly benefiting OLTP systems. Concurrently, NoSQL databases (e.g., Cassandra, MongoDB) emerged, designed to exploit distributed storage architectures like HDFS and object stores. Cloud providers accelerated this shift by offering pay-as-you-go storage tiers, democratizing access to high-performance infrastructure. Today, databases choosing best storage solution is no longer constrained by physical limits but by architectural trade-offs—balancing consistency, availability, and partition tolerance (CAP theorem) while optimizing for cost and performance.
Core Mechanisms: How It Works
The interaction between a database and its storage layer hinges on three critical mechanisms: data placement, caching strategies, and durability guarantees. Data placement dictates how records are distributed across storage media. For instance, a B-tree index in PostgreSQL may reside on fast NVMe drives, while archived logs are tiered to cheaper HDDs or cold storage. Caching layers—such as the Linux page cache or database-specific buffers (e.g., MySQL’s InnoDB buffer pool)—mitigate latency by keeping frequently accessed data in memory. Meanwhile, durability mechanisms like write-ahead logging (WAL) ensure crash recovery by persisting changes to stable storage before acknowledging transactions.
The storage subsystem also influences concurrency control. Databases using row-level locking (e.g., PostgreSQL) benefit from low-latency storage to minimize lock contention, while systems employing MVCC (Multi-Version Concurrency Control) rely on efficient snapshot isolation mechanisms, often implemented via copy-on-write storage techniques. Emerging architectures, such as log-structured merge trees (LSM) in RocksDB, optimize for write-heavy workloads by appending to a log before compacting data, reducing random I/O overhead. Understanding these mechanisms is essential for evaluating whether a storage solution can handle the database’s concurrency model without becoming a bottleneck.
Key Benefits and Crucial Impact
The right storage choice directly impacts database performance, cost efficiency, and operational resilience. A well-optimized storage stack can reduce query latency by orders of magnitude, cut infrastructure costs by 30–50% through tiered storage, and eliminate downtime by ensuring data durability. Conversely, mismatched storage leads to cascading failures: slow disks trigger timeouts, leading to connection pools exhaustion, and ultimately, degraded user experiences. The financial stakes are equally high—over-provisioned storage inflates CapEx by millions annually, while under-provisioned systems incur hidden costs in lost productivity and abandoned transactions.
Beyond technical metrics, databases choosing best storage solution affects long-term agility. Storage-agnostic databases (e.g., CockroachDB, YugabyteDB) abstract persistence details, allowing seamless migration between cloud providers or hardware generations. This flexibility is critical for organizations facing regulatory changes or scaling demands. Conversely, tightly coupled architectures (e.g., Oracle RAC) lock users into specific storage configurations, complicating future upgrades. The choice of storage thus extends beyond immediate performance—it shapes the database’s lifecycle.
"Storage is the silent partner in database performance. Get it wrong, and your queries will suffer—no matter how well you’ve tuned the SQL."
— Martin Kleppmann, Author of Designing Data-Intensive Applications
Major Advantages
- Performance Optimization: Aligning storage latency with database access patterns (e.g., NVMe for OLTP, HDDs for batch processing) reduces I/O bottlenecks by 40–70%.
- Cost Efficiency: Tiered storage (hot/warm/cold) cuts costs by up to 60% by moving inactive data to cheaper media without sacrificing accessibility.
- Scalability: Distributed storage (e.g., Ceph, MinIO) enables horizontal scaling, allowing databases to grow beyond single-node limits.
- Durability and Compliance: RAID configurations and synchronous replication ensure data survival during hardware failures, meeting regulatory requirements like GDPR or HIPAA.
- Future-Proofing: Storage-agnostic designs (e.g., using abstraction layers like Apache Arrow or Kafka) simplify migrations to new hardware or cloud providers.

Comparative Analysis
| Storage Type | Use Case & Trade-offs |
|---|---|
| Block Storage (EBS, iSCSI) | Best for: Traditional RDBMS (PostgreSQL, MySQL), low-latency transactions. Pros: Predictable performance, fine-grained control over IOPS. Cons: High cost at scale, manual provisioning complexity. |
| Object Storage (S3, Azure Blob) | Best for: NoSQL (DynamoDB, MongoDB), cold data archives, analytics. Pros: Scalable, cost-effective for large datasets, built-in versioning. Cons: Higher latency (~10–100ms), not ideal for frequent small writes. |
| File Storage (NFS, Lustre) | Best for: Polyglot persistence (e.g., mixing PostgreSQL with file-based caches). Pros: Flexible, supports shared access across nodes. Cons: Metadata operations can become bottlenecks. |
| Persistent Memory (PMem, SCM) | Best for: High-performance in-memory databases (e.g., Redis, SAP HANA). Pros: Near-DRAM speeds, byte-addressable storage. Cons: High cost, limited capacity compared to SSDs/HDDs. |
Future Trends and Innovations
The next frontier in databases choosing best storage solution lies in converging storage and compute. Technologies like storage-class memory (SCM) (e.g., Intel Optane) are eliminating the von Neumann bottleneck by placing data closer to processing units, enabling databases to achieve microsecond-level latency for in-memory operations. Meanwhile, distributed transactional storage (e.g., Google Spanner, CockroachDB) is redefining consistency models by combining timestamp-based ordering with globally distributed storage, ensuring strong consistency without sacrificing availability.
Cloud-native innovations will further blur the lines between storage and database services. Serverless databases (e.g., AWS Aurora Serverless) automatically scale storage tiers based on workload, while data mesh architectures treat storage as a productized service, allowing teams to select best-of-breed solutions without vendor lock-in. Additionally, AI-driven storage optimization—where machine learning predicts access patterns to pre-fetch data—will become mainstream, reducing latency by up to 90% in predictive workloads. Organizations must prepare for a future where storage is no longer a passive layer but an active participant in database performance tuning.

Conclusion
Databases choosing best storage solution is a multidimensional challenge that demands a balance of technical expertise and strategic foresight. The optimal choice depends on workload characteristics, budget constraints, and long-term scalability goals. Ignoring storage nuances can lead to suboptimal performance, inflated costs, or even system failures—yet many organizations still treat it as a secondary concern. The key is to evaluate storage through the lens of the database’s operational patterns: transactional systems need low-latency durability, analytical workloads benefit from high-throughput tiers, and hybrid architectures require flexible, multi-tiered designs.
As storage technologies evolve—from NVMe and SCM to AI-optimized tiers—the landscape will continue to shift. The databases choosing best storage solution in 2024 will prioritize performance predictability, cost elasticity, and architectural agility. By adopting a systematic approach—assessing access patterns, benchmarking storage options, and future-proofing for emerging trends—organizations can turn storage from a passive infrastructure component into a competitive advantage.
Comprehensive FAQs
Q: How do I determine if my database’s storage is a bottleneck?
Monitor metrics like disk I/O latency (avg. read/write times), queue depth (pending I/O operations), and cache hit ratios. Tools like iostat, vmstat, or database-specific metrics (e.g., PostgreSQL’s pg_stat_activity) can identify slow queries or storage-related timeouts. If latency exceeds 10–20ms for critical operations, or if the storage subsystem is maxed out (e.g., 100% utilization), it’s likely a bottleneck.
Q: Should I use SSDs for all database workloads?
No. While SSDs excel for random I/O (e.g., OLTP transactions), they may not justify the cost for sequential scans or cold data. HDDs remain cost-effective for batch processing, and object storage (e.g., S3) is ideal for archival or infrequently accessed data. A tiered approach—hot data on NVMe/SSD, warm on HDD, cold in object storage—often yields the best cost-performance balance.
Q: How does RAID configuration affect database performance?
RAID levels trade performance, capacity, and redundancy differently:
- RAID 0: Striped (no redundancy), maximizes throughput but risks data loss.
- RAID 1/10: Mirrored, offers high durability but halves capacity.
- RAID 5/6: Distributes parity, balances performance and redundancy but suffers from write penalties.
Q: Can I mix storage types in a single database cluster?
Yes, but it requires careful orchestration. For example:
- PostgreSQL can use SSDs for tables and HDDs for WAL archives via tablespaces.
- MongoDB supports storage engines like WiredTiger (SSD-optimized) or RocksDB (LSM-tree for writes).
- Cloud databases (e.g., Aurora) automatically tier data between high-performance and cold storage.
Q: What are the risks of using cloud object storage for a database?
Cloud object storage (e.g., S3) introduces:
- Higher latency (~50–100ms vs. <1ms for block storage).
- Limited transactional support—most object stores lack ACID guarantees for small, frequent writes.
- Vendor lock-in if using proprietary services (e.g., DynamoDB’s global tables).
- Cost spikes for frequent small operations (e.g., S3’s GET/PUT charges).
Q: How do I future-proof my database storage?
Adopt these strategies:
- Abstraction layers: Use storage-agnostic databases (e.g., CockroachDB) or middleware (e.g., Vitess) to decouple storage from the database engine.
- Modular architectures: Design for horizontal scaling (e.g., sharding) to avoid single-storage bottlenecks.
- Automated tiering: Leverage tools like AWS Storage Gateway or Ceph’s RBD to dynamically move data between tiers.
- Benchmarking: Regularly test storage performance under production-like loads to identify degradation early.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.