How AI Exploring Intersection Generative Models Is Redefining Creative Boundaries
The fusion of artificial intelligence with generative modeling has birthed a paradigm where algorithms don’t just replicate patterns—they navigate the intersections of disparate domains. From reconstructing molecular structures using visual data to generating symphonic compositions from abstract paintings, AI exploring intersection generative models operates at the nexus of creativity, science, and computation. The breakthrough lies in its ability to transcend disciplinary silos, producing outputs that would be impossible through traditional siloed approaches.
Consider the case of AlphaFold, which leveraged generative techniques to predict protein folding—a problem that had stymied biochemists for decades. Or the DALL·E 3 variant that synthesizes 3D objects from textual descriptions, blending natural language processing with spatial reasoning. These aren’t isolated examples but symptoms of a broader shift: AI-driven generative systems are now capable of exploring intersections where human expertise alone falters. The implications span industries, from drug discovery to urban planning, where the synthesis of heterogeneous data becomes the key to innovation.
The most compelling aspect of this evolution isn’t just the outputs but the process. Traditional generative models operated within fixed domains—text generating text, images generating images. Today’s intersection generative models are designed to translate between modalities, whether it’s converting musical scores into tactile haptic feedback or rendering climate data as interactive art installations. The result is a toolkit that doesn’t just augment human creativity but redefines the boundaries of what can be imagined.

The Complete Overview of AI Exploring Intersection Generative Models
AI exploring intersection generative models represents a convergence of multiple AI subfields: diffusion models, transformer architectures, and multimodal learning. At its core, the approach involves training models on paired or unpaired datasets that span different data modalities—text, images, audio, scientific simulations—to enable cross-domain generation. The distinguishing factor is the model’s ability to map between these domains without rigid constraints, allowing for emergent behaviors that mimic human-like associative thinking.
For instance, a model trained on medical imaging and patient records might generate synthetic case studies that preserve statistical properties while introducing novel diagnostic scenarios. Similarly, an intersection model in fashion could take inspiration from historical textiles, modern sustainability metrics, and real-time weather patterns to design adaptive clothing. The flexibility stems from architectures like CLIP (Contrastive Language-Image Pre-training) or Gato, which learn joint embeddings across modalities, enabling zero-shot or few-shot generalization to unseen intersections.
Historical Background and Evolution
The roots of AI exploring intersection generative models trace back to the late 20th century with early work in neural-symbolic integration, where researchers attempted to bridge statistical learning with rule-based systems. However, the field gained traction in the 2010s with the rise of deep generative models like GANs (Generative Adversarial Networks) and VAEs (Variational Autoencoders). These models excelled at single-modality generation but lacked the cross-domain adaptability needed for true intersection exploration.
Table of Contents
- The Complete Overview of AI Exploring Intersection Generative Models
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What distinguishes intersection generative models from traditional generative AI?
- Q: Can these models handle completely novel intersections not seen in training data?
- Q: How are intersection generative models being used in scientific research?
- Q: What are the biggest ethical concerns with intersection generative AI?
- Q: Are there open-source tools available for experimenting with intersection generative models?
The turning point arrived with the introduction of transformer-based architectures (e.g., BERT, Vision Transformers) and diffusion models, which demonstrated unprecedented capacity for multimodal understanding. Projects like Make-A-Video (2022) and Imagen pushed boundaries by generating videos from text, while Stable Diffusion variants extended this to 3D asset creation. The current wave of intersection models builds on these foundations by incorporating contrastive learning (e.g., CLIP) and reinforcement learning from human feedback (RLHF) to refine outputs for specific applications, such as scientific hypothesis generation or personalized therapy design.
Core Mechanisms: How It Works
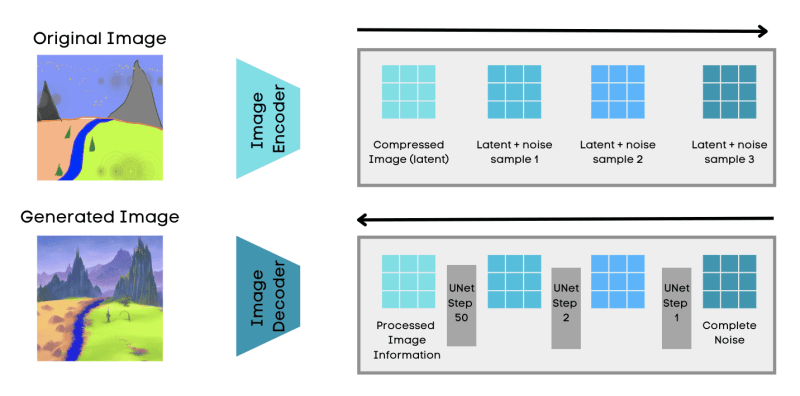
The technical backbone of AI exploring intersection generative models relies on three interconnected components: multimodal embeddings, conditional generation, and latent space navigation. Multimodal embeddings (e.g., via CLIP) create a shared representational space where text, images, and other data types coexist. Conditional generation then uses these embeddings to produce outputs constrained by user-provided prompts or domain-specific rules. For example, a model might generate a molecular structure conditioned on both a target protein function (text) and a preferred chemical stability pattern (image-based).
Latent space navigation—enabled by techniques like StyleGAN or Diffusion Models—allows the model to traverse high-dimensional spaces where subtle variations in input (e.g., adjusting a color palette in an image) correlate with meaningful changes in output (e.g., altering a drug’s solubility). This is particularly valuable in intersection generative models, where the goal isn’t just replication but exploration. For instance, a model exploring the intersection of architecture and climate science might generate thousands of building designs optimized for local weather patterns, each with unique aesthetic and functional trade-offs. The model’s ability to sample this space efficiently—without exhaustive manual iteration—is what makes it a transformative tool.
Key Benefits and Crucial Impact
The practical applications of AI exploring intersection generative models are reshaping industries by enabling design exploration at scales previously unimaginable. In drug discovery, models can simulate molecular interactions across chemical libraries and biological pathways, accelerating the identification of candidate compounds. In urban planning, intersection models might generate thousands of neighborhood layouts optimized for traffic flow, green spaces, and economic viability. Even in art and entertainment, the technology allows creators to prototype interactive narratives or virtual worlds by blending textual themes with visual and auditory elements.
The broader impact extends to democratizing creativity. Historically, interdisciplinary collaboration—such as merging engineering with art—required rare talent and extensive resources. Today, intersection generative models lower the barrier for individuals to explore hybrid domains. A musician without formal coding skills can generate soundscapes from visual data, or a biologist can visualize genetic sequences as abstract sculptures. This shift isn’t just about efficiency; it’s about expanding the scope of human expression.
"The most profound technologies are those that disappear into the fabric of creation, allowing humans to focus on the 'what' rather than the 'how.' Intersection generative models are poised to do just that—by turning the intersections of disciplines into playgrounds for innovation."
— Dr. Maria Chen, Director of Computational Creativity Lab, MIT Media Lab
Major Advantages
- Cross-Domain Synthesis: Combines disparate data types (e.g., text + medical imaging) to generate novel outputs, such as synthetic patient cases for training AI in healthcare.
- Accelerated Discovery: Explores vast solution spaces in fields like materials science or climate modeling, identifying optimal designs or hypotheses faster than traditional methods.
- Personalization at Scale: Adapts outputs to individual preferences or constraints (e.g., generating fashion designs tailored to body metrics and cultural trends simultaneously).
- Reduced Cognitive Load: Automates the tedious process of bridging disciplinary gaps, allowing experts to focus on interpretation and refinement.
- Ethical Flexibility: Enables controlled exploration of sensitive intersections (e.g., bias mitigation in hiring algorithms by generating diverse candidate profiles from resumes and interview data).
Comparative Analysis
| Traditional Generative Models | AI Exploring Intersection Generative Models |
|---|---|
| Operate within single modalities (e.g., text-to-text, image-to-image). | Seamlessly integrate multiple modalities (e.g., text + 3D + physics simulations). |
| Limited to pre-defined tasks (e.g., style transfer, super-resolution). | Supports open-ended exploration (e.g., "Generate a sustainable city layout inspired by Baroque architecture"). |
| Requires separate models for each domain. | Uses unified architectures (e.g., transformers with shared embeddings). |
| Outputs are constrained by training data distribution. | Can extrapolate to novel intersections via latent space navigation. |
Future Trends and Innovations
The next frontier for AI exploring intersection generative models lies in dynamic adaptation and real-time collaboration. Current models rely on static datasets, but future systems will incorporate online learning to refine outputs as new data streams in—imagine a model generating real-time architectural adjustments based on live sensor data from a construction site. Additionally, human-AI co-creation platforms will emerge, where users interactively steer generative processes, blending their intuition with the model’s exploratory capabilities.
Another critical direction is interpretable intersection modeling. Today’s systems often operate as "black boxes," making it challenging to explain how a model arrives at a specific output. Future advancements in attention mechanisms and causal inference will provide transparency into the model’s decision-making, particularly in high-stakes fields like healthcare or finance. This will not only build trust but also enable debugging and customization at a granular level. The ultimate goal is to transition from generative assistance to generative partnership, where AI and humans collaboratively explore intersections beyond either could navigate alone.

Conclusion
AI exploring intersection generative models is more than a technological evolution—it’s a redefinition of how we approach problem-solving across disciplines. By breaking down the walls between text, images, audio, and scientific data, these models unlock possibilities that align with human curiosity rather than rigid frameworks. The key to their success lies in their ability to learn from intersections rather than just replicate them, fostering a symbiosis between artificial and human intelligence.
As the technology matures, the challenge will shift from what can be generated to how we integrate these outputs into the world. Ethical frameworks, interdisciplinary collaboration, and continuous refinement will determine whether these tools amplify creativity or exacerbate existing biases. One thing is certain: the era of intersection generative AI has only just begun, and its trajectory will be shaped by those who dare to explore the spaces between.
Comprehensive FAQs
Q: What distinguishes intersection generative models from traditional generative AI?
A: Traditional generative AI (e.g., GANs, VAEs) operates within a single domain, such as generating images from noise or text from text. Intersection generative models are designed to bridge multiple domains—like combining text prompts with 3D spatial data or medical imaging with patient records—to produce outputs that integrate heterogeneous information. This cross-domain capability enables applications like designing drugs based on both chemical structures and biological pathways.
Q: Can these models handle completely novel intersections not seen in training data?
A: Yes, but with caveats. Models trained on latent space navigation (e.g., diffusion models) can extrapolate to some extent, generating plausible outputs for unseen intersections by interpolating between learned patterns. However, performance degrades for highly abstract or unprecedented combinations. Techniques like few-shot learning or reinforcement learning are being developed to improve generalization to novel intersections.
Q: How are intersection generative models being used in scientific research?
A: In biology, models generate synthetic protein structures or simulate molecular dynamics to predict drug interactions. In climate science, they create hypothetical climate scenarios by blending historical data with future projections. Materials science uses these models to design new alloys or polymers by exploring intersections of mechanical properties, thermal conductivity, and cost constraints.
Q: What are the biggest ethical concerns with intersection generative AI?
A: The primary concerns include bias amplification (if training data reflects historical inequities), misinformation (when models generate convincing but false intersections, e.g., deepfake historical events), and intellectual property (who owns outputs generated from copyrighted data?). Additionally, the black-box nature of some models raises questions about accountability in high-stakes decisions, such as medical diagnostics or legal judgments.
Q: Are there open-source tools available for experimenting with intersection generative models?
A: Yes, several frameworks and libraries support intersection modeling, including:
- Stable Diffusion (with custom LoRA fine-tuning for multimodal tasks).
- Hugging Face Diffusers (for diffusion-based intersection generation).
- CLIP (for zero-shot cross-modal retrieval).
- BlenderBIM (for architecture/engineering intersections).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Filmfestivalcircuit.